Last updated
SOLUTION 08
DATA SCIENCE AS A SERVICE
Data science as a service delivers predictive machine learning inside your own perimeter, with governance, versioning and audit trails built in from day one. CCA automates feature engineering and model iteration so a first model arrives in weeks, rather than after a six-month data preparation effort or a long search for scarce specialist hires.
Trapped Between Two Undesirable Choices
In-House Builds Are Slow. Generic AI Is Unreliable.
The choice: Build an In-House Data Science Team
What it means: Hire and wait months for scarce data science talent, then wait again for models to reach production.
Why it fails
In-House Data Science Build
- Six-month typical wait for a first model
- 80% of project time spent on data preparation alone
- Six months or more just to hire a data science specialist
- Dependent on a single scarce hire, with no redundancy
The choice: Rely on Off-the-Shelf GenAI
What it means: Adopt generic, topical AI tools that aren’t built for auditable, regulated financial outcomes.
Why it fails
Off-the-Shelf GenAI Tools
- Not built for auditable, regulated financial outcomes
- Lacks model versioning, audit trail, and feature visibility
- Topical, but less reliable than proven predictive use cases
- No structural guarantee your data stays within your perimeter
A Predictive ML, Deployed-in-Place Strategy
Xpanse deploys inside your cloud or data centre - connecting directly to your data as a Data Science as a Service platform that turns raw data into governed, production-ready predictive models in days, not months.
Speed to Commercial Value, Not Months of R&D
Business units see outputs the next morning, not after a six-month build. Xpanse automates the data science work that normally consumes 80% of project time.
Models iterate in minutes - toggle variables, adjust for cost and duration, and re-run - so this is a continuously improving capability, not a one-shot project.
Significantly Reduces Delivery Risk
- Deployed inside your cloud or data centre - your data never leaves your perimeter
- Audit trail, model versioning, and feature visibility built in from day one
- Aligned to Consumer Duty, DORA, SMCR, and SS1/23
- Scales across multiple models simultaneously, with no dependency on a scarce data science hire
- Priced as OpEx, not CapEx - easier to approve than a permanent hire
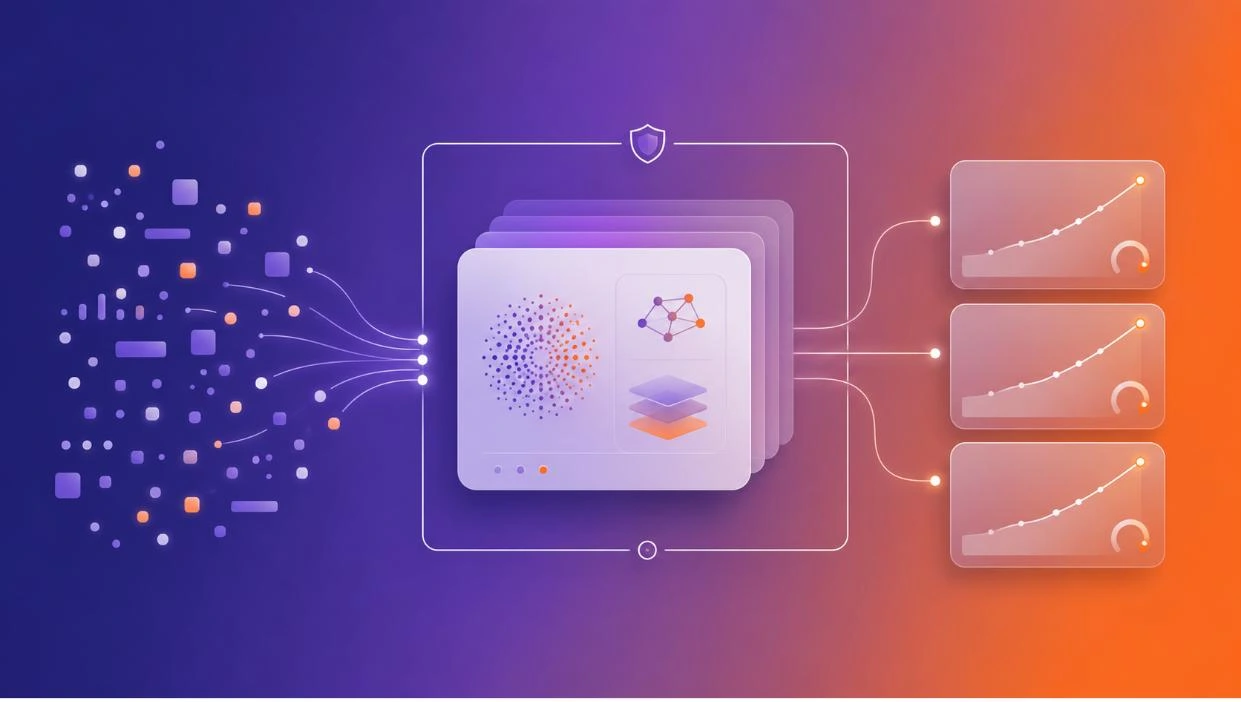
Predictive ML, End to End
From raw data to governed, production-ready predictions inside your own environment.
Your Data
Stays inside your perimeter
Xpanse Predictive ML
Automated, governed data science
Production Models
Auditable, traceable outcomes
Purpose-Built Components, Working as One
Automated Feature Engineering
Automatically designs and tests thousands of features from raw data, removing the manual data-prep bottleneck.
Model Iteration Engine
Toggle variables, adjust for cost and duration, and re-run in minutes - models that keep improving, not a one-shot deliverable.
In-Perimeter Deployment
Runs inside your own cloud or data centre, so sensitive financial data never leaves your environment.
Governance & Audit Trail
Built-in model versioning, audit trail, and feature visibility, aligned to Consumer Duty, DORA, SMCR, and SS1/23.
“Xpanse essentially unclogged Data Science for us. We can see the first iteration of models the next day.”
Martin Graham, Director of Insights & Analytics, Virgin Media Ireland
What the Solution Delivers
Predictive ML in Days
First model within days, not the typical six-month wait.
Proven Financial Use Cases
Investment signal identification, cross-sell/up-sell propensity, fraud and AML pattern detection, credit risk and default prediction, client churn and retention risk.
Auditable, Traceable Outcomes
Every model is versioned and inspectable, built for regulated environments.
Measurable ROI
+250% ROI on cross-sell, 2000% ROI on fraud detection, and €650k a month in retained revenue.
Outcomes That Matter to the Business
Cut Time to First Model from Months to Days
Reduce Data Prep Effort by 80%
Prove ROI: +250% Cross-Sell, 2000% Fraud Detection
Keep Data Inside Your Perimeter, By Design
Scale Predictive ML Without a Permanent Hire
Frequently asked questions
How quickly will we see a first model?
Business units see outputs the next morning rather than after a six-month build, with a first model typically within days. Models then iterate in minutes by toggling variables and adjusting for cost and duration. As Martin Graham, Director of Insights & Analytics at Virgin Media Ireland, put it: “Xpanse essentially unclogged Data Science for us. We can see the first iteration of models the next day.”
Does our data leave our environment?
No. Xpanse deploys inside your own cloud or data centre, so sensitive financial data never leaves your perimeter. The data science runs where the data lives, and data stays inside your environment end to end.
Do we need to hire data scientists to use it?
No. It scales across multiple models simultaneously with no dependency on a scarce data science hire, and it is priced as OpEx rather than CapEx, which is easier to approve than a permanent headcount commitment.
What governance and audit support is included?
Model versioning, an audit trail and feature visibility are built in from day one rather than retrofitted, and the approach is aligned to Consumer Duty, DORA, SMCR and SS1/23.
Which use cases does it cover?
Proven financial services use cases include investment signal identification, cross-sell and up-sell propensity, fraud and AML pattern detection, and credit risk modelling.
What makes this faster than building in-house?
Automated feature engineering designs and tests thousands of features from raw data, removing the manual data preparation bottleneck. CCA frames the problem plainly: 85% of AI projects never reach production, and 80% of project time is spent on data preparation alone.
Start with one question: what business outcome do you want to predict?
Talk to a consultant about connecting Xpanse to your environment for a first model within days.
Talk to a consultant